Learning Safe, Optimal, and Real-Time Flight Interaction With Deep Confidence-Enhanced Reachability Guarantee
Abstract
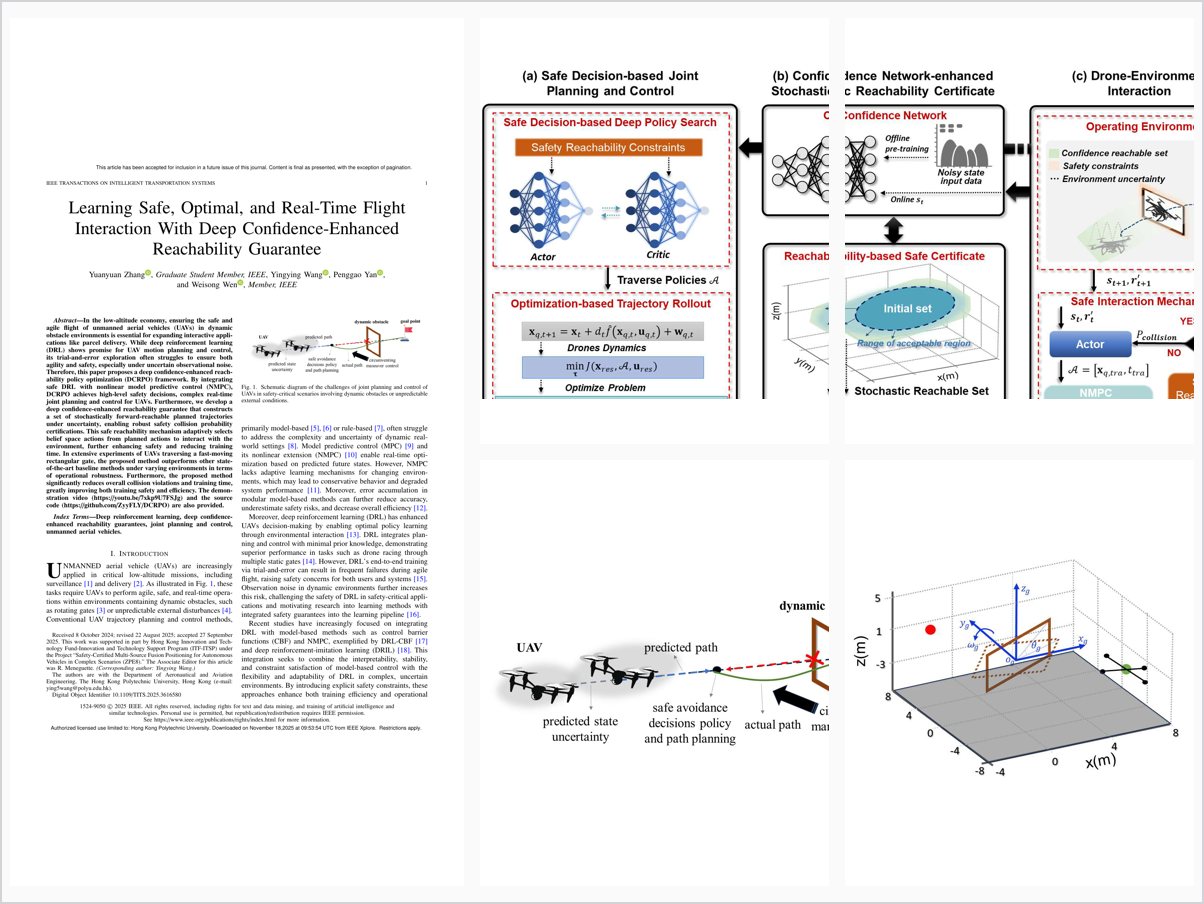
In the low-altitude economy, ensuring the safe and agile flight of unmanned aerial vehicles (UAVs) in dynamic obstacle environments is essential for expanding interactive applications like parcel delivery. While deep reinforcement learning (DRL) shows promise for UAV motion planning and control, its trial-and-error exploration often struggles to ensure both agility and safety, especially under uncertain observational noise. Therefore, this paper proposes a deep confidence-enhanced reach-ability policy optimization (DCRPO) framework. By integrating safe DRL with nonlinear model predictive control (NMPC), DCRPO achieves high-level safety decisions, complex real-time joint planning and control for UAVs. Furthermore, we develop a deep confidence-enhanced reachability guarantee that constructs a set of stochastically forward-reachable planned trajectories under uncertainty, enabling robust safety collision probability certifications. This safe reachability mechanism adaptively selects belief space actions from planned actions to interact with the environment, further enhancing safety and reducing training time. In extensive experiments of UAVs traversing a fast-moving rectangular gate, the proposed method outperforms other state-of-the-art baseline methods under varying environments in terms of operational robustness. Furthermore, the proposed method significantly reduces overall collision violations and training time, greatly improving both training safety and efficiency. The demonstration video (https://youtu.be/7xkp9U7FSJg) and the source code (https://github.com/ZyyFLY/DCRPO) are also provided.
Problem Addressed
Deep reinforcement learning for UAV motion planning and control in dynamic obstacle environments struggles to ensure both agility and safety through trial-and-error exploration, especially under uncertain observational noise.
Key Contributions
- DCRPO framework combining safe DRL for high-level policy search with nonlinear model predictive control for low-level rolling optimization
- Deep confidence-enhanced stochastic reachability certificate using SCNet for dynamic state confidence estimation
- Stochastically forward-reachable trajectory sets enabling robust safety collision probability certification under uncertainty
- Adaptive belief-space action selection improving training safety and reducing training time
Conclusions
In experiments of UAVs traversing a fast-moving rectangular gate, DCRPO outperforms state-of-the-art baselines in rewards, safety metrics, and goal achievement rates, consistently maintaining high safety under varying environmental noise levels while significantly reducing collision violations and training time. Its reachability analysis increases computation time, and effectiveness has only been verified in simulation; real-world experiments are left for future work.